
声明:本脚本仅用于学习交流,请勿用于非法途径,造成的任何后果与本人无关使用三方库:requests,threadpool,socket
测试目标:自己的博客网站
使用的字典自己去hub上面找找
程序原理:
函数将字典读入到lists里面,然后多线程取出每个域名前缀,用requests库请求,如果返回响应码为200则表示网站存在,当然,表示网站存在的响应码不止有200。
程序运行结果:
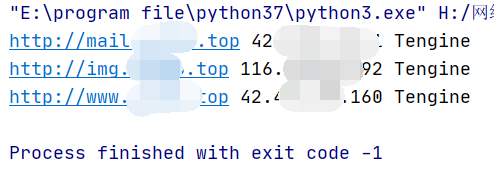
这里会把域名对应的ip和空间也同时输出,怎么实现呢,ip输出是利用socket.gethostbyname()这个函数将域名转成ip,输出域名的空间是通过调用返回头中的SERVER的值。
代码如下:
#!/usr/bin/python
# -*- coding: UTF-8 -*-
'''
作者:木尤
声明:本脚本仅用于学习交流,请勿用于非法途径,造成的任何后果与本人无关
要点:需要安装requests,threadpool,socket这三个库
'''
import requests,threadpool,socket
url1="http://"
#url2是你需要爆破的主域名,前面必须加.
url2=".域名"

ff=open("./success.txt.txt",'w+')
lists=[]
##下面的gc.txt是你的子域名的字典,将字典的内容加载到lists
def zd():
    f=open("./sub_full.txt",'r')
    for d in f:
        dir=d.strip()
        lists.append(dir)

#调用字典的域名访问,看是否为200
def bp(str):
    try:
        res=requests.get(url1+str+url2,timeout=3)
        if res.status_code==200:
            ff.write(url1+str+url2+'\n')
            print(url1+str+url2,socket.gethostbyname(str+url2),res.headers['Server'])
    except:
        pass
zd()
#这个是线程数,一次调用字典的50个执行
pool=threadpool.ThreadPool(50)
reqs=threadpool.makeRequests(bp,lists)
[pool.putRequest(req) for req in reqs]
pool.wait()
来源:freebuf.com 2021-01-04 18:07:15 by: muyou8
正文完